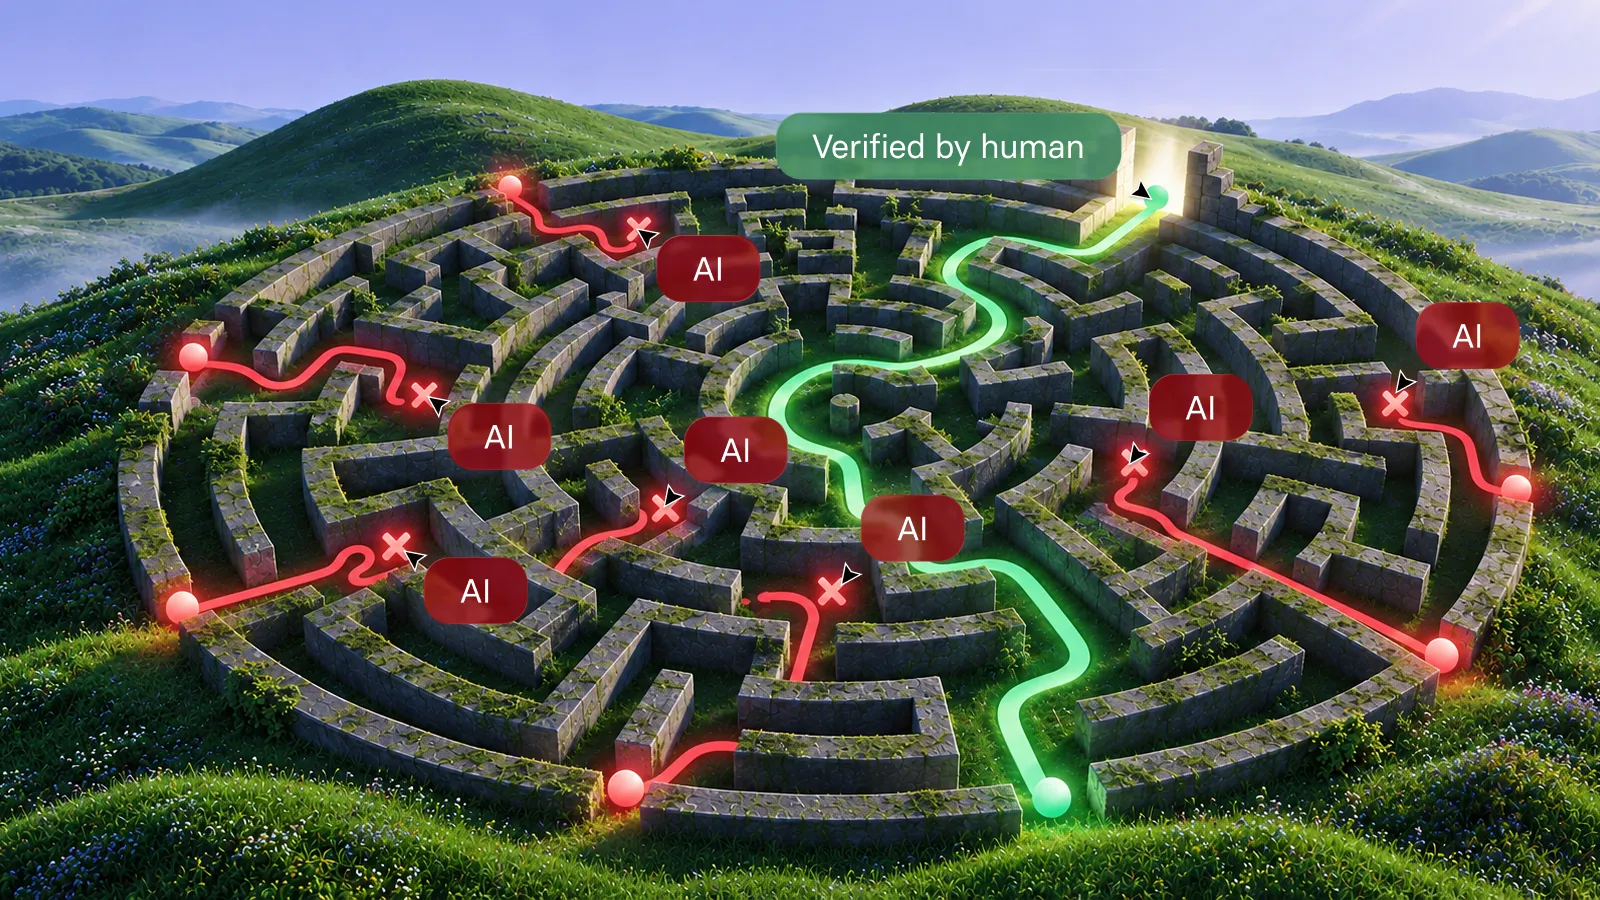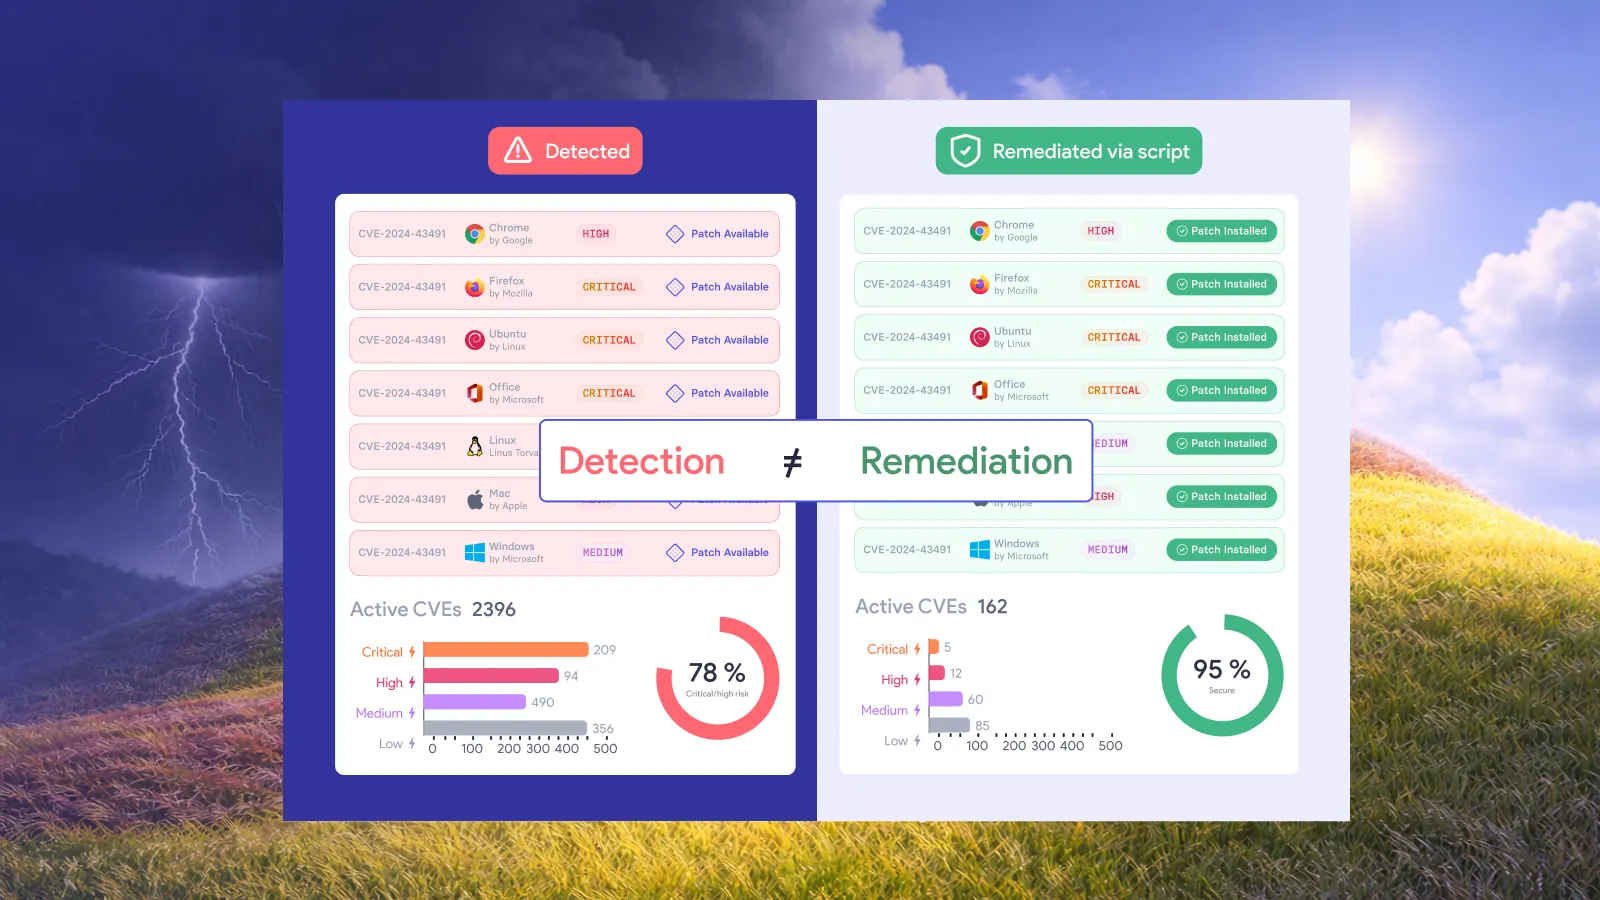


An AI coding agent changes a function. The original exploit stops working. The test turns green.
Before accepting the repair, the reviewer still needs to know what changed. Did the fix correct the vulnerable behavior, reject one particular input, or disable a feature that users need?
Adversarial testing for AI-generated fixes means deliberately challenging a proposed repair with relevant misuse cases beyond the original reproducer. It should sit alongside functional tests and code review, with results tied to the exact version being considered for release.
The practical question is whether the change meets its security objective while preserving required behavior. A single passing test cannot answer every part of that question.
What is adversarial testing?
Adversarial testing evaluates a system using inputs or actions chosen to expose failures. It examines what happens when someone deliberately challenges the system’s assumptions, permissions, or expected behavior.
Google’s guidance for generative AI describes testing inputs selected to provoke problematic outputs, including relevant edge cases and failure modes. Google’s adversarial testing guide.
For an AI-generated security fix, the object under review is different: the modified software, rather than only the model’s response.
A reviewer might ask whether an authorization change protects other affected operations, whether a parser still accepts legitimate documents, or whether a resource limit applies consistently across supported entry points.
Those questions need explicit expected results. “Try to break it” is a starting intention, not an acceptance criterion.
Testing should take place in an authorized environment with defined boundaries. Use synthetic data, limit access to unrelated systems, and give the evaluator a clear stopping condition.
What two recent studies tell us
Two October 2026 preprints examine different weaknesses in how AI-generated repairs are evaluated.
On the Reliability of LLM-Based Vulnerability Patching Benchmarks, published October 7, uses 112 historical bugs across 84 open-source projects. It distinguishes passing a proof-of-concept test from passing tests derived from developers’ fixes.
The authors show that evaluation conditions can change reported outcomes. Their sample was deliberately selected for reproducible builds and useful test artifacts. It does not establish a general failure rate for AI-generated patches. Developer-derived tests also remain incomplete evidence, rather than proof of correctness. Benchmark reliability preprint.
The October 5 preprint Does AI Help Cyber Attackers or Defenders? examines subsequent attacks as a separate evaluation step. Another tested exploit succeeded in 92 of 524 defender test intervals after the original exploit had been stopped.
That denominator needs care. The intervals were not independent and included intermediate software states, not just final submitted repairs. The result should not be presented as a failure rate for production patches. The selected environments also limit generalization. Subsequent-attack preprint.
These studies support a narrower conclusion: a claim about repair quality should identify which behavior was tested and under what conditions.
Separate the questions a repair must answer
For a repair review, use separate acceptance criteria for the original defect, required functionality, and additional security cases.
The following worksheet is a recommended operating method, not a certification standard.
| Review question | Evidence to collect | What the result does not establish |
|---|---|---|
| Does the original reproducer demonstrate the defect before the change? | Recorded result against the identified vulnerable version | That the reproducer covers every affected path |
| Does the proposed fix stop the original failure? | Result against the exact candidate version | That alternative inputs cannot trigger related failures |
| Does required behavior still work? | Relevant functional and regression results | That the security boundary is correct |
| Do additional security cases meet their expected outcomes? | Results for documented identities, inputs, states, and entry points | Resistance to every untested scenario |
| Was the tested change actually deployed? | Artifact identity and deployment verification | That a different build or configuration has the same properties |
Keep these results separate in the review record.
A functional failure should not disappear inside an aggregate pass percentage. An interrupted security test should remain unresolved. If a test never reached the affected operation, explain that before using its result to support release.
How to run adversarial testing on an AI-generated fix
1. Write the security objective before reviewing the patch
Describe the behavior that must be prevented without referring only to the supplied exploit.
For an access-control problem, an objective might be:
A user must not retrieve records belonging to another tenant through the affected service.
Then record the legitimate behavior that must remain available:
An authorized user must still retrieve records from their own tenant.
These statements give reviewers something concrete to evaluate. They also make a proposed feature restriction visible as a tradeoff rather than allowing it to pass unnoticed as a complete repair.
Assign an owner for the acceptance decision. The person reviewing the code and the person accepting an operational restriction may have different responsibilities.
2. Establish a trustworthy baseline
Identify the vulnerable version, candidate version, environment, configuration, and test inputs.
Confirm that the original reproducer reaches the relevant operation and demonstrates the expected failure on the vulnerable version. If it does not, investigate the mismatch before treating a later green result as evidence.
For each test, record what constitutes success. An error response, for example, might be the intended rejection of an unauthorized request. It might also indicate that the application failed to start.
The distinction belongs in the test result, not in an assumption made afterward.
Use a clean, reproducible test environment where possible. Retain enough information for another engineer to rerun the relevant checks without reconstructing the setup from a chat transcript.
3. Preserve the legitimate workflow
Select functional tests with the feature owner.
Cover the operations users depend on, including important boundary conditions. For a document-processing change, that could mean supported formats, valid large files, expected error handling, and downstream consumers of the output.
Do not count rejecting all requests as success when the service is supposed to remain available.
If temporarily disabling a feature is the chosen response, document it as a mitigation. Record the operational impact, owner, review date, and work required for a permanent correction.
The distinction between a temporary restriction and a complete repair also matters when considering constrained AI remediation. The acceptance criteria should reflect the action actually taken.
4. Choose additional tests from the security objective
Build a small, reasoned set of cases around the affected boundary.
For each case, write:
• The assumption being challenged.
• The relevant user, input, or application state.
• The expected permitted or rejected behavior.
• The evidence that will demonstrate the result.
For an authorization repair, consider the identities and operations covered by the same policy. For a validation change, consider supported input variations and the point at which validation occurs.
Avoid adding large numbers of nearly identical cases merely to increase the test count. A useful review explains why each case could reveal a different problem.
Keep the scope proportionate to the change and its potential impact. A repair touching shared authorization logic deserves a broader review than a narrowly isolated change.
5. Separate repair assistance from acceptance
An AI agent can help propose tests, explain a diff, or identify assumptions for a reviewer to challenge. Its description of what passed should point to retained execution evidence.
For this workflow, acceptance should remain under a separately controlled review process. The repair-producing agent should not be able to redefine the security objective or silently remove a required check.
An independent reviewer can still use AI assistance. The important separation is control over the criteria and interpretation of the results, not simply choosing a different model.
Record failures plainly. If a test could not run, say why and identify who must resolve it.
6. Bind the decision to the tested version
Capture the candidate’s commit or artifact identifier, the relevant configuration, and the test results used for approval.
If the code changes after testing, determine which results need to be rerun. Do not carry an approval forward merely because the filename or ticket number stayed the same.
After deployment, confirm that the accepted artifact is active in the intended environment. The patch verification checklist covers the operational evidence needed at that stage.
Pre-release evaluation and deployment verification answer different questions. Both should be visible in the handoff.
A worked example: fixing access to customer records
Consider a hypothetical application where a user can request a customer record outside their tenant.
An AI-generated change blocks the identifier used in the original reproducer. That test now passes, but the stated objective concerns tenant isolation, not one identifier.
The reviewer asks the application owner to confirm the intended access rules. Together, they select synthetic records and authorized test accounts representing the relevant roles.
The review checks whether the user can access their own records, whether cross-tenant requests are rejected, and whether other supported operations enforce the same rule. Each check records the expected result before execution.
Suppose the additional tests show that one operation still permits cross-tenant access. The original test result remains valid, but the repair does not meet the acceptance criteria.
The ticket should say exactly that. It should not describe the candidate as a complete fix with a minor testing issue.
Alternatively, the team might temporarily disable the affected operation while preparing a correction. That can be an explicit operational decision, with its limitations documented and verified.
This is an illustrative scenario, not a reported incident or a claim about any particular model. It shows why the security objective must be broader than the input that first exposed the problem.
What should the release decision contain?
A useful decision record should be short enough to review and specific enough to reproduce.
Include:
• The defect and intended security outcome.
• The exact candidate version and relevant environment.
• Required legitimate behavior.
• Completed security and functional checks.
• Failed, interrupted, or untested cases.
• Any temporary restrictions and their owners.
• The approver and deployment verification requirement.
Use bounded conclusions. “The candidate met the documented criteria in the test environment” says more than “AI verified the fix.”
Testing provides evidence for a decision under stated conditions. Google’s broader security engineering guidance similarly treats adversarial testing as a way to assess resistance to particular attacks, not as a route to perfect security. Building Secure and Reliable Systems.
Where an important uncertainty remains, give it an owner and a next action. A clearly recorded gap is more useful than a confident summary that conceals it.
Frequently asked questions
Is adversarial testing the same as regression testing?
No. Regression testing checks whether existing expected behavior continues to work after a change. Adversarial testing deliberately challenges security assumptions or failure conditions. A repair review needs both: blocking an unwanted action does not establish that legitimate use still works.
Does stopping the original exploit mean a vulnerability is fixed?
It establishes that the tested exploit no longer succeeded under the tested conditions. Acceptance should also consider the underlying security objective, required functionality, and relevant additional cases. The scope of the conclusion should match the scope of the evidence.
Can the same AI agent write the fix and its tests?
It can assist with both, but that should not give it sole control over acceptance. Keep required criteria and final review separately controlled. Retain execution results so reviewers can assess what ran, what passed, and what remains unresolved.
How many adversarial tests are enough?
There is no universal count. Choose cases based on the affected behavior, potential impact, supported entry points, and important variations in identity or state. Explain the coverage and its limits. A larger collection of repetitive cases does not automatically provide stronger evidence.
What if an urgent fix cannot wait for a full review?
Make the emergency decision explicit. Apply the organization’s emergency change process, perform the feasible checks, record residual uncertainty, and assign follow-up validation. If a temporary restriction is used, verify that restriction and keep the permanent remediation task open.
Add acceptance criteria to the next AI-assisted repair
Choose one AI-generated security fix currently under review.
Before approving it, write the security outcome it must achieve, the legitimate behavior it must preserve, and the additional cases that could challenge the proposed change.
Attach the results to the exact candidate version. If the only evidence is that the original test turned green, the review is not finished.